What Hallmark proves
For the pretrained TinyLlama response, see the LLM proof statement.
This page explains the classifier proofs exercised by make e2e.
Classifiers use direct-STWO Circle STARKs, with Hallmark’s dedicated SHA-256/integer/classifier circuits. The LLM uses SASH’s specialized Circle STARK application. Architecture shows the flow; Circle classifier details give concrete parameters and ownership. The proofs establish the following logical relation.
For a fixed integer classifier and a particular prompt, the proof checks that running that classifier on those bytes gives the stated pass/block verdict.
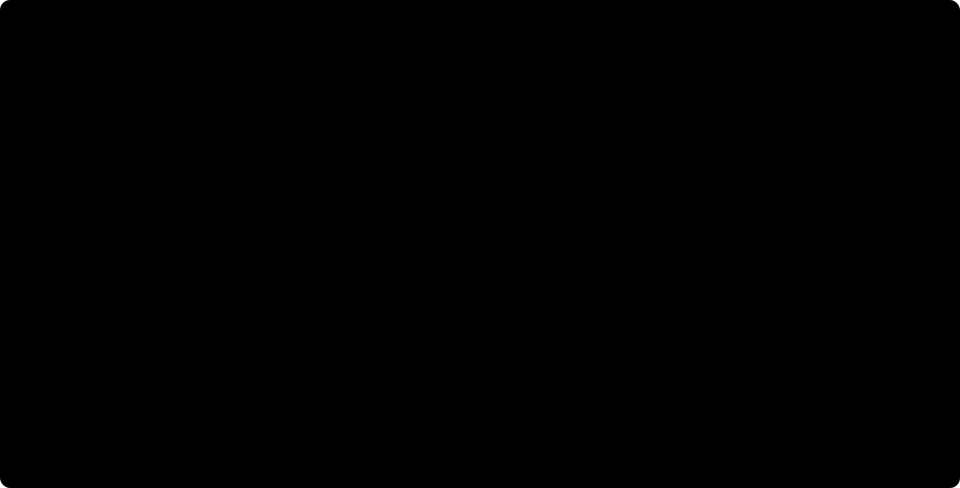
That is the claim exercised by make e2e. The demo makes three proofs
per request: one for a literal rule, one for a trained MLP and one for a trained
CNN. A separate verifier checks each proof. The caller then combines their
verdicts with all-pass. Here, enrolled means chosen and pinned before proving.
The demo does that locally; it does not authenticate a production enrollment authority.
A concrete example
Consider a synthetic prompt with an active instruction and a quotation:
The CNN's task is to distinguish the active action from quoted text. A proof of its passing verdict means the exact enrolled integer CNN computed a score below its enrolled threshold on this complete prompt. It does not mean that reading a note is safe in every setting, that the labels are correct, or that the CNN will handle different wording well.
If the same model blocks a prompt, that computation can also have a valid proof.
Proof validity and classifier approval are separate outcomes. In the demo,
cnn-block and rule-block both have three valid proofs and release: false.
A bad proof causes the run to fail; a correctly proved block is an expected result.
The statement checked by a circuit
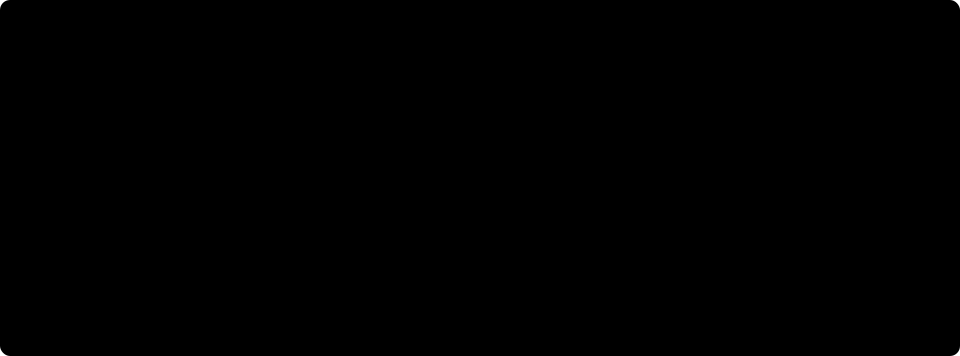
Let x be the complete prompt encoded as UTF-8 bytes, F the fixed integer
classifier, t its threshold and v its verdict. For the MLP and CNN:
The rule's verdict is 1 exactly when no BAD byte sequence occurs anywhere in
x, including across its chunk boundaries. The shared demo admits 0–96 bytes;
longer inputs fail before proving. It never proves only a silently truncated
prefix.
The circuit constrains a witness satisfying all of the following:
- The active bytes, lengths and padding describe the complete admitted input.
- The canonical input encoding and its salted SHA-256 digest match the public input digest, under the fixed input profile.
- Every operation of the fixed integer graph holds, including range checks, scaling/rounding, activations, masks and aggregation where applicable.
- The public verdict equals the graph's threshold decision.
Training exports the learned weights into circuit constants. The proof checks integer inference, not the float training process or the history of how those weights were obtained. Native evaluation and quantization checks are separate software checks.
What is public, and what is trusted?
| Item | Where it comes from | What checks it |
|---|---|---|
| Prompt bytes and opening salt | Caller-owned transcript opening | Caller reconstructs the expected input digest; the circuit checks its witness against that digest |
| Classifier weights and graph | Fixed rule and frozen seed-17 integer exports, compiled into each circuit | Caller enrollment pins program, public preprocessing and proof parameters; the proof checks the compiled relation |
| Threshold and verdict | Enrolled classifier and caller's expected computation | Caller pins the threshold; circuit enforces the decision |
| Request context and classifier identity | Caller-owned request, transcript and enrollment | Caller reconstructs these public fields; proof verification binds them to this proof |
| Circle enrollment | Program, preprocessing roots and concrete parameters, pinned before proving | Fresh proof-only verifier checks against caller-owned enrollment |
release |
Three checked verdicts | Host code computes rule_pass AND mlp_pass AND cnn_pass |
Each proof has 100 logical public integers: 32 bytes of context digest, 32 bytes of classifier identity, 32 bytes of input digest, then unit count, chunk count, encoded signed threshold and verdict. Circle transports them as 103 M31 values: two limbs replace the 32-bit threshold, and zero/one wires provide two further values. No reduction of 32-bit integers modulo M31 is accepted. The score itself is not a public field. The witness includes input bytes, salt, encoding/mask data and intermediate values; model weights are public circuit constants in this demo.
Public binding is not the same as in-circuit reconstruction. The circuits recompute the input digest and classifier arithmetic. They range-check the context and classifier digest bytes, but do not recompute the full transcript context, classifier identity or derivation of the per-classifier salt. Those links are established by the caller's reconstruction and its trusted mapping from program to compiled circuit and enrollment. A digest or enrollment supplied only by an untrusted prover cannot establish that mapping.
All three classifiers use the same caller-owned prompt and request context. Their input digests differ because their profiles and derived salts differ. The caller reconstructs each separately; it does not simply compare three digest strings for equality.
What the verifier actually does
There are two stages, both required:
- Bind the statement. circle_backend.py checks the caller-pinned program/preprocessing/model mapping, reconstructs public inputs from the caller-owned opening, and checks the exact classifier roster. The helper currently reruns native classifiers for expected verdicts. This produces verification jobs; it is not yet cryptographic acceptance.
- Check the proofs. A fresh circle-verify process checks each serialized STWO proof using enrollment and public inputs. It receives no witness, checkpoint or native trace. It shares the STWO/AIR implementation with the prover; it is not an independently developed verifier. Any failure prevents a successful result.
Nine proofs means one per classifier for each of three requests, not an aggregate proof of training or policy. The run rejects 63 changed public statements, 18 cross-request substitutions and three invalid rosters. Trace parity and the separate constraint-failure study supplement those real proofs; they do not establish independent security qualification.
What a successful run does not prove
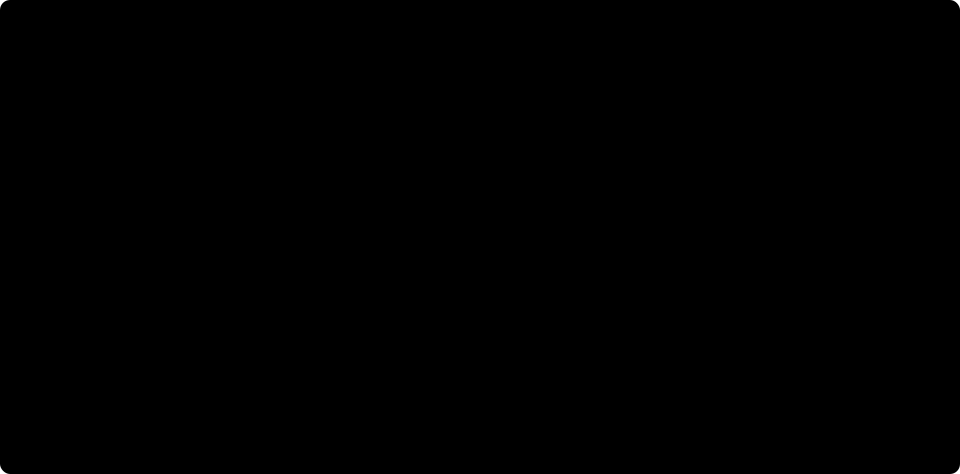
- LLM inference provenance. No LLM is run. The response is authored fixture text. Its bytes and a model-identity reference are included in the caller's transcript/context, but no proof shows that model produced that response.
- Response classification. These three classifiers inspect the prompt. Binding a response into the context does not mean its content was classified.
- Classifier quality beyond the synthetic screen. Correct execution can faithfully reproduce a mistaken prediction. Training labels, generalization and policy suitability need their own evidence.
- Private inference. The caller sees the transcript, and local artifacts contain witnesses. Public model constants and locally generated salts are not a private deployment. This is an opened-input research path, not a hiding claim.
- Production trust. Compiler/program-to-preprocessing enrollment, independent security/hiding review and an operational verifier adapter remain qualification gates.
release: true means only that the three proved classifier verdicts pass. The
run retains qualified_backend: false and hardware_claim: "not-accepted".
For exact circuits, see the Circle source map. For reproduction and evidence, see the demo.